Elephant Scale · Advance Registration
Become a legal engineer.
Legal AI Engineering is an emerging specialization. Employers are beginning to hire for these skills,
but practical, integrated engineering training remains relatively uncommon. This is that training:
the person who can actually build AI for legal work — and prove it holds up.
Two hands-on days — three if you add the Deep Dive. Ingest messy
legal data, make it searchable, add retrieval that cites its sources, keep it private on a local
model and prove nothing left the machine, then measure a document review well enough to defend
the numbers. You finish with a working repository, not notes.
An Elephant Scale course · Intermediate to Advanced · Live online, 9:00–16:00 US Central · 2-day Core,
plus a 1-day Deep Dive scheduled separately
taught by Mark Kerzner, the engineer who builds FreeEed
Dates are being set now. Advance registration is open — registrants choose from the dates
first and hear before anyone else.
Get the dates first
No payment, no commitment. You are telling us you want the dates and which format suits you.
Why this course exists
Legal work is being handed AI faster than anyone is being trained to build it. Training exists for the pieces — legal technology, eDiscovery, AI engineering, “AI for legal”
generally. What is uncommon is the integration: one build path from messy data to something you can
be cross-examined on. That is what this course is.
Two claims run through every module, because they are the two a legal engineer actually has to make:
“Nothing left the building.”
“Here is exactly what the system did, and you can re-run it.”
What the postings actually say
Nine postings, six employers, read on 11 November 2026 — a snapshot, not a market study.
At four of those six employers, the job titled Legal AI Engineer is a
J.D.-gated role: they want a lawyer who already practises, and no course can get you one.
The roles that want what this course teaches — build the pipeline, prove the privacy,
measure the review — exist at the same employers, pay comparably or better, and are
titled something else: forward-deployed engineer, AI automation engineer, AI solutions
engineer. Knowing which half of the market to apply to is the first hour of the course, and
it is worth more than another lab.
These nine postings are what we read on one day, not a measurement of the market. Two of them
have since been filled or closed. We will say the same thing in class, with the postings in
front of you.
Two ways in
Nobody is born a legal engineer. People arrive from one of two directions, and the course is
built to take either one.
Coming from legal — paralegals, eDiscovery and litigation-support professionals
You already have the half that takes years to acquire: you know what the work actually is,
what a privilege call costs, and why a production has to be right the first time. What this
adds is the building — so that the next time a tool cannot do what the matter needs,
you are the person who makes one.
And the straight version, because you should have it before you register rather than
after: the labs are hands-on Python. You will write code. You will write it with an AI
assistant beside you — that is a prerequisite of the course, not a crutch, and it is how
this job is genuinely done now. But the course as it runs today is pitched
intermediate-to-advanced. If you have never written a line, say so on the form. If
enough of you do, we will run a paced cohort that starts further back. We would far rather
build that than have you spend day one lost.
Coming from engineering — developers and AI engineers moving into legal tech
You have the stack. What you are missing is the domain — and in legal work the constraints
that decide whether a system is usable are mostly not the technical ones.
No legal background required — privilege, defensibility, production and the
rest are taught in context, as the problems they actually are. You will finish able to talk
to lawyers about the thing you built without either side translating.
Also squarely in scope: engineers already at legal-tech companies who have
the platform but keep hitting the legal-domain depth they were never taught.
Buying for a team? A private cohort is the better route — your own data-handling
constraints, your stack, your schedule. Say so on the form.
What you build
The Core — two days, the full build path:
- ·Ingest what legal data actually looks like1,400+ file types, email and PST, scanned paper, load files, and the embedded metadata that matters. De-duplication as a deliberate choice, not a default.
- ·Make it findableFull-text search and indexing, relevance, metadata and date filtering. The bedrock primitive: find anything inside everything.
- ·Retrieval that cites its sourcesRAG over legal documents, and why retrieval rather than fine-tuning for sensitive material: the model never swallows the documents. Chunking, embeddings, and above all provenance.
- ·Keep it private, and prove itWhere data actually goes when it reaches a cloud assistant. Serving local models (Ollama / vLLM, OpenAI-compatible) and monitoring outbound traffic so you can certify what did not leave. And choosing honestly: vendor-approved cloud, government cloud under FedRAMP/StateRAMP/CJIS authorization, and local or air-gapped are all accepted in practice. The skill is defending the choice you made, not assuming one answer.
- ·Defensible reviewRecall, elusion, precision, ground-truth validation. Measuring a review, documenting it, and pinning the model and settings so someone can re-run it in a year and get the same result.
- ·The capstoneAssemble it end to end over a deliberately messy corpus and score it against a structured rubric. It is assessed, and the bar is the same for everyone.
You will not learn RelativityOne, CoCounsel or Harvey here. You will build the layer
underneath them — which is how you end up able to say what any of them is doing to your
documents, what it is not doing, and what you still owe a court either way. The platforms are
a week of configuration once you have this. It does not run in the other direction.
The Deep Dive — one day, scheduled separately (it assumes the Core): ship the thing.
You come back with the work you built in the Core — and if your laptop has moved on since,
we rebuild it at the start of the day.
The Core is the whole build path on its own. The Deep Dive adds artifacts, not the parts that
were held back.
Document production, containerized private on-prem packaging, an agentic workflow with a human
checkpoint designed in rather than promised, attacking your own guardrails and watching them
hold, and a governance audit against the AI-regulation landscape.
Electives, booked on their own: investigative AI — entities, relationships, timelines —
and on-prem deployment at scale in regulated environments.
Why it is taught from here
Every design decision in these labs was made once already, under load, in a product that ships
— which is why the course can tell you why a thing is built that way and not just
that it is. That product is FreeEed: Apache-2.0, on-prem eDiscovery —
extraction across 1,400+ file types, OCR, imaging, PST/OST, Solr/Lucene search, review and
export. It is the reference architecture the course points at, and you can download it and run
it today.
Nothing in the course requires it. The labs are self-contained Python over synthetic
corpora, there is no vendor account and no licence, and FreeEed is Apache-2.0 — there is
nothing here to buy. It is in the course because it is a real system you can open up, not because
it is ours.
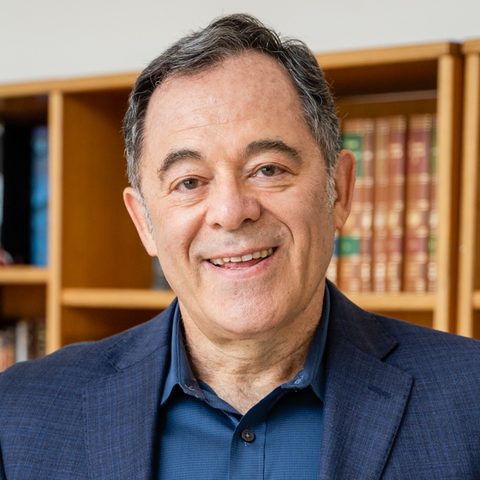
Mark Kerzner — the author of FreeEed, the Apache-2.0
eDiscovery platform the labs are designed against. He teaches this course for Elephant Scale.
The design decisions you are taught are the ones a shipping product had to make. That is the
whole reason it is taught from here rather than from a syllabus.
Prerequisites
- ·Comfortable with Python and basic APIs— as the course runs today. Coming from the legal side and not there yet? Register anyway and say so on the form — see “Two ways in” above.
- ·Bring your own AI subscriptionA working account with a frontier assistant (Claude, ChatGPT, Gemini or equivalent). You will use it as a coding assistant throughout, the way you will on the job. No lab depends on it and no lab needs an API key — but anyone who does not already work this way starts a day behind.
- ·Helpful: familiarity with LLMs at a user levelNo ML background required — the mental model is built in the course.
- ·No legal background requiredThe legal concepts you need are taught in context.
- ·A modern laptop and reliable internetPlus a local model runtime (Ollama / vLLM) for the privacy labs.

